Prepared Parquet observation input
HealDA reads prepared observation archives. Raw observation decoding, calibration, quality-control production, and archive construction are outside the package boundary. A directory is compatible only when its layout, Arrow schema, channel identities, and normalization metadata match the selected loader and checkpoint.
There are two sources, and a recipe uses one or the other:
| source | root | loader | sensor vocabulary |
|---|---|---|---|
| NNJA | NNJA_ROOT |
observations/loaders/nnja_*.py |
observations/sensors_nnja.py |
| UFS replay (legacy) | UFS_OBS_PATH |
observations/loaders/ufs.py |
observations/sensors.py |
NNJA is the source the checkpoints are trained on. The UFS replay archive is an earlier source, kept for older runs and described at the end. Each source is self-contained: an NNJA run does not need the UFS archive.
The two sources hold different observations, prepared differently. The UFS replay
archive holds the observations GSI thinned and quality controlled in the UFS replay;
the NNJA archive holds the full NCEP record, which healda's loaders screen and thin.
Their sensors, channel vocabularies (Global_Channel_ID), normalization statistics
and quality control differ, so a checkpoint works only with the source it was trained
on.
Observation pipeline
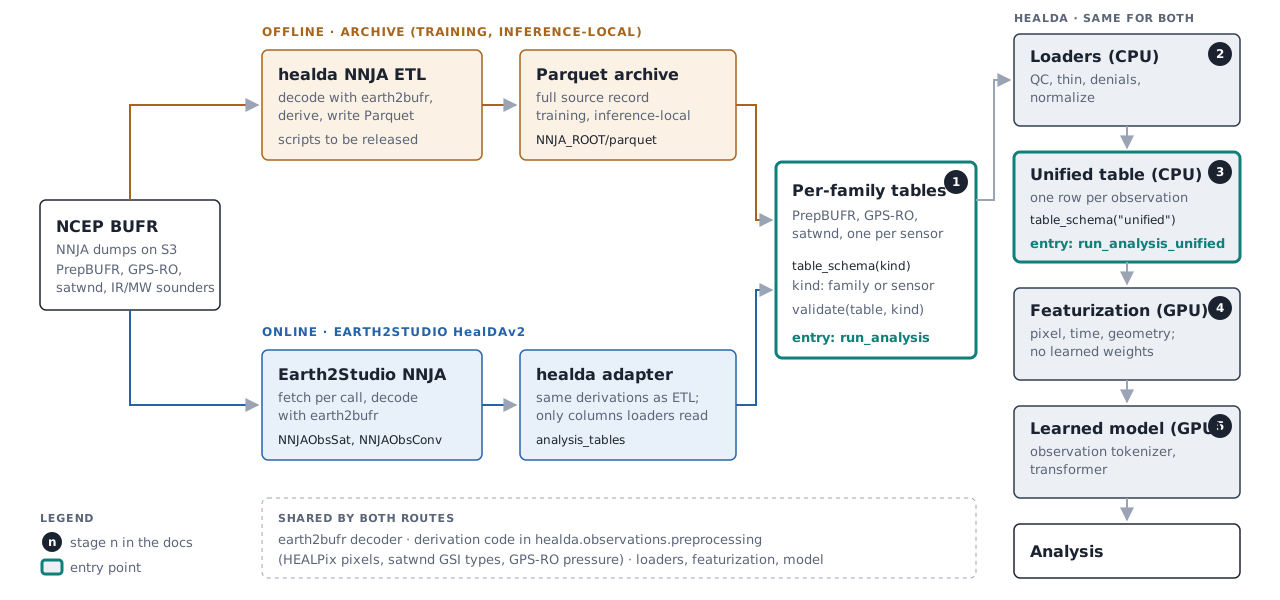
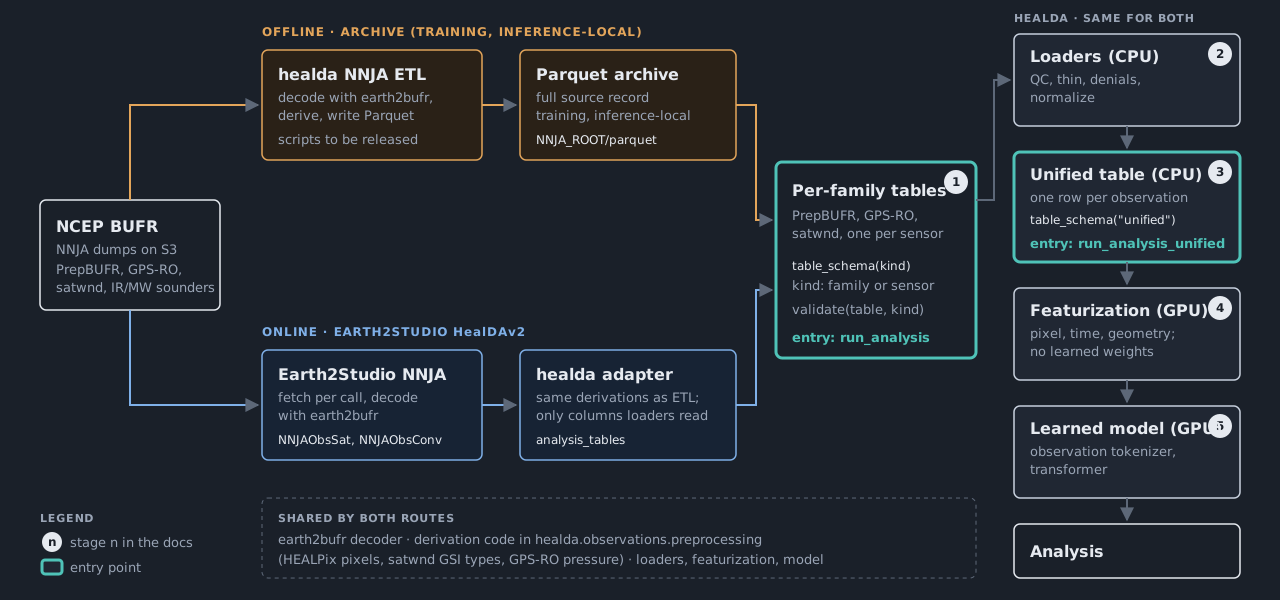
Observations reach the model through five sequential stages:
- Per-family tables (CPU): the raw observations, one table per family, PrepBUFR,
GPS-RO and satellite winds, and one per satellite sensor. Contract:
schema.table_schema(kind), withir_channelsfor a satellite sensor. To change it, replace stages 1 and 2 together. - Loaders (CPU): screen and quality control, thin, drop dated channel denials and
provider-flagged footprints, convert units and normalize, then emit stage 3. To change
it, see
build_obs_loaderindatasets/da/tasks.py,observations/loaders/nnja_*.pyandobservations/loaders/combined.py. - Unified table (CPU): the processed observations, one table for every family, one
row per observation, values normalized. Contract:
schema.table_schema("unified"). To plug in here, seeDAModel.run_analysis_unified. - Featurization (CPU or GPU, no learned weights): the HEALPix pixel at the model
level, time, geometry and position features, and the values and ids packed into a
UnifiedObservation. To change it, seeTransformV2.transform_observationsindatasets/da/transform.pyandobservations/preprocessing/features.py. - Learned model (GPU): the observation tokenizer embeds the features with the
channel, platform and observation-type ids, then the transformer. See
tokenize_observationsinmodels/dit.pyandObsTokenizerFiLMinmodels/obs_embedding/point_embed_v2.py.
The entry points:
| input | enters at | contract | healda runs |
|---|---|---|---|
NNJA archive under NNJA_ROOT, read by healda-inference-local |
1, on disk | table_schema |
2 to 5 |
per-family tables, DAModel.run_analysis(times, prepbufr_tables=..., gpsro_tables=..., satwnd_tables=..., satellite_tables=...) |
1, in memory | table_schema |
2 to 5 |
unified table, DAModel.run_analysis_unified(times, table) |
3 | table_schema("unified") |
4 and 5 |
- NNJA archive: the layout is in NNJA archive.
- Per-family tables: per-cycle tables in the archive schemas, keyed by the cycle of
the file they come from. Earth2Studio's
HealDAv2builds them withadapters.e2s_nnja.analysis_tables, which derives the archive columns with the same code as the offline ETL that produced the training data. The loaders thin, quality control and normalize them as they do the archive. - Unified table: one table; concatenate several with
pyarrow.concat_tables. The caller does thinning, quality control and normalization. Each analysis reads the rows whoseDA_windowis one of its frames' windows, and passes them to stage 4 unchanged. The caller supplies ids and normalized values consistent with the model it runs: for the HealDA v2 checkpoint, the packaged vocabulary and statistics,loaders.combined.channel_table(nnja_conv=True); a modified model defines its own.run_analysis_unifiedraises for aGlobal_Channel_ID,Platform_IDorObservation_Typeoutside the network's embedding tables, and for asensor_idthe transform does not group.
New channels or platforms need a model whose embedding tables cover their ids.
NNJA archive
Set NNJA_ROOT. Files live under NNJA_ROOT/parquet in the following
layouts, one per observation family; Building the NNJA archive gives the
scripts that write them:
parquet/<sensor>/YYYYMMDD.parquet
parquet/ir48/<sensor>/YYYYMMDD.parquet
parquet/cycles/YYYY/gdas.YYYYMMDD.tHHz.prepbufr.nr.parquet
parquet/gpsro_v3/YYYY/gdas.YYYYMMDD.tHHz.gpsro.tm00.bufr_d.parquet
parquet/satwnd_v2/YYYYMMDD.parquet
The columns, Arrow types and field metadata each family is read with are in
healda.observations.schema: table_schema("prepbufr"), table_schema("gpsro"),
table_schema("satwnd"), and table_schema(sensor, ir_channels) for a satellite
sensor. Each field's metadata description gives its unit and meaning; a field with
healda.required = false is read when present. nnja_balloon_drift also reads XDR,
YDR and HRDR, and nnja_withhold_stations reads SID.
from healda.observations import schema

print(schema.table_schema("cris", "ir32"))
schema.validate(table, "prepbufr")  # or "gpsro", "satwnd", a sensor name, "unified"
schema.validate(table, "cris", ir_channels="ir32")
validate raises ValueError naming every missing or mistyped column.
An NNJA run needs only NNJA_ROOT. The conventional channel vocabulary, its
validity bounds and its normalization statistics all ship with the package.
Matching a trained checkpoint
The v2 checkpoint was trained on the NNJA archive, built from the
NNJA BUFR feeds, with the v2-nnja-latlon-dense configuration in
healda/cli/train.py. Settings named below take that configuration's values, among them:
- Satellite sounders are thinned at HEALPix level 7,
nnja_sat_thin_hpx_level. - Satellite winds are thinned at HEALPix level 6,
nnja_satwnd_thin_hpx_level. - PrepBUFR reports with quality marks up to 3 are kept,
nnja_max_quality_mark. - Radiosonde levels sit at their drifted position and time,
nnja_balloon_drift. Conventional files then also needXDR,YDRandHRDR. - Radiosonde and pibal winds without
ZOBtake the standard-atmosphere height of theirPOB,nnja_pressure_height_fill="sonde".
A checkpoint gives its intended results only on data prepared the same way. Data from another source, such as a near-real-time feed, has to reproduce the processing below. Columns can be renamed to the archive's, but the values have to mean the same thing. Fine-tuning or training a new model on differently prepared data is outside this contract.
Two places in the code show the format in full:
- The loaders,
observations/loaders/nnja_*.py, define each family's archive rows and what is done to them on load. observations/adapters/e2s_nnja.pyconverts Earth2Studio's NNJA data into those archive rows. It renames columns, derives what the archive derives with the same code (for example the GPS-RO pressure below), and reads ATMS antenna temperature rather than brightness temperature. Its functions return per-cycle tables that the loaders take through theirtable_sourcearguments, so nothing has to be written to disk. It is the model to follow for a new source.
Inputs the model was trained with
-
Satellite sounders, from every platform below that was flying. Each sensor's platforms are those in its normalization file under
observations/normalizations/nnja/.- ATMS: Suomi NPP, NOAA-20, NOAA-21
- AMSU-A: NOAA-15 to NOAA-19, MetOp-A, MetOp-B, MetOp-C
- AMSU-B: NOAA-15 to NOAA-17 (training only, no longer flying)
- MHS: NOAA-18, NOAA-19, MetOp-A, MetOp-B, MetOp-C
- AIRS: Aqua
- IASI: MetOp-A, MetOp-B, MetOp-C
- CrIS: Suomi NPP, NOAA-20, NOAA-21
-
Conventional PrepBUFR reports of temperature, humidity, wind and surface pressure from:
- radiosondes, dropsondes and pibals
- aircraft, including the restricted AMDAR, ACARS and TAMDAR reports
- surface land stations (synoptic and METAR)
- surface marine stations (ships and buoys)
- wind profilers, NEXRAD VAD winds and RASS
- scatterometers (ASCAT, QuikSCAT, ERS, WindSat)
The report types each variable accepts are
T_REPORT_TYPES,Q_REPORT_TYPES,UV_REPORT_TYPESandPRESSURE_REPORT_TYPESinloaders/nnja_conventional.py. -
GPS radio occultation bending angle, from every satellite in the archive.
- Satellite winds (atmospheric motion vectors) from the SATWND archive. Their PrepBUFR copies are dropped.
Each of these sources contributes positively to analysis skill. For the best analyses, provide all of them at inference.
Conventional observations
This covers PrepBUFR reports, GPS radio occultation and satellite winds, and
concerns their vertical coordinates. The observation featurization requires a
valid height and pressure on every conventional observation and drops rows that
lack either (preprocessing/filtering.py, QCLimits in observations/sensors.py):
- height: 0 to 60,000 m
- pressure: 0.5 to 1,100 hPa for GPS radio occultation, and
conv_min_pressure_hpa(1 hPa) to 1,100 hPa for everything else
Some families report both coordinates. For the others the loader fills one in.
-
PrepBUFR conventional (
loaders/nnja_conventional.py): pressure isPOBand height isZOB. Rows withoutZOBare dropped, except:- Scatterometer winds report a 10 m wind and no
ZOB. Their height is set to 10 m. - Surface winds of report types 280, 281 and 287 (
nnja_surface_winds) get heightELV+ 10 m, as in GSI. Types 282 (ATLAS buoys) and 284 are excluded and dropped, because theirPOBis a nominal 1013 hPa or reduced from sea-level pressure rather than measured. - Radiosonde and pibal winds (report types 220 and 221) take the US Standard
Atmosphere height of their
POB(nnja_pressure_height_fill="sonde").
- Scatterometer winds report a 10 m wind and no
-
GPS radio occultation (
loaders/nnja_gpsro.py) reports height only. Height isheit_at_impact_m. Pressure isblended_pressure_5km_hpa, whichderive_level_coordinatesinpreprocessing/gpsro_pressure.pyderives from the occultation's own refractivity, with no model background. Below 5 km it is 0.8 standard atmosphere plus 0.2 dry hydrostatic, and above 5 km dry hydrostatic. - Satellite winds (
loaders/nnja_satwnd.py) report pressure only. Pressure isassigned_pressure, the producing centre's final height assignment. Height is that pressure's US Standard Atmosphere 1976 altitude, floored at 0 m.
The checkpoint was trained on the coordinates above. A coordinate from a different algorithm, even a more accurate one, such as a GPS pressure taken from a model background, changes the model's input; analyses made with such coordinates have not been evaluated.
Satellite sounders
What the wide satellite files (loaders/nnja_wide.py) must hold, and what the
loader changes on load:
- Channels are identified by the instrument's own channel number. A loaded
model's
DAModel.ir_channelslists the infrared channels its recipe reads, and it reads no others. For the trained configuration that is their32preset, 32 channels each for AIRS, IASI and CrIS (ir_channel_presetinpreprocessing/ir_spectral.py). Microwave sounders are read on all their channels. - Microwave sounders carry no antenna-to-brightness-temperature correction.
ATMS is read from
antenna_temperature. The AMSU-A, AMSU-B and MHS archives name their columnbrightness_temperature, but apart from NOAA-15 and NOAA-16 AMSU-A it holds antenna temperature. Supply these values uncorrected. - Hyperspectral infrared: IASI is archived as spectral radiance and CrIS as
integer-coded radiance. The loader converts both to brightness temperature by
monochromatic Planck inversion (
brightness_temperatureinpreprocessing/ir_spectral.py), with CODATA 2018 constants and the channel wavenumbers defined in that module. AIRS is archived as brightness temperature. To supply IASI or CrIS brightness temperature instead, compute it with that inversion (its constants are earth2studio'sPLANCK_C1/PLANCK_C2). Other constants, channel wavenumbers or a band correction give values that differ from the training data. Write it asbrightness_temperature__ch_NNNNNcolumns (NNNNNthe five-digit channel number) with field metadatannja.value_unit = K, asobservations/adapters/e2s_nnja.pydoes; the loader then reads it without an inversion. - Geometry: longitude is -180 to 180 in the archive and moved to 0 to 360 on load. Satellite zenith angle is an unsigned magnitude in the archive, and the loader gives it GSI's sign, negative on the first half of the scan.
At inference
healda.inference and healda-inference-local apply the recipe in the checkpoint's
loop.json and remove two further groups of observations
(inference_filters in observations/system.py):
- Provider quality flags: footprints that the data provider flags for bad
calibration or corrupted data are dropped. The flags per sensor are
SOURCE_QUALITY_FLAGSinobservations/schema.pyand their bitsSOURCE_FLAG_BITSinloaders/nnja_wide.py: CrIS scan and field-of-view quality, IASIQGFQ, and ATMS scan, granule and channel quality. A flag applies only where the input carries its column. Earth2Studio'sNNJAObsSatcarries them in its per-channelqualitycolumn (ATMS channel quality and CrISNFQF, from which the field-of-view flag is derived) and in its footprint columnsscan_quality,granule_qualityandfootprint_quality. - Channel denials: channels known to be degraded are dropped over a date range,
listed in
observations/denials.csv.
Invariants
- Timestamps are timezone-naive UTC values and archive partitions cover the requested context window.
- Coordinates and physical values use the units expected by the loader.
- Arrow types are safely castable to the package schema.
- Global channel, local channel, sensor, and platform identities remain stable.
- Every channel has finite normalization and validity metadata.
- Row-group statistics for time-selection columns are present when required.
UFS replay archive (legacy)
Set UFS_OBS_PATH to a local directory or object-store URL. The root contains:
Each observation file holds the columns of get_combined_observation_schema() in
observations/schema.py, one row per observation value, values in physical units; the
loader normalizes them.
channel_table.parquet maps every Global_Channel_ID to normalization and
identity metadata. It must contain Global_Channel_ID, min_valid,
max_valid, sensor_id, is_conv, name, mean, and stddev. IDs must be
unique and consistent with the package vocabulary.